The problem
Voice interfaces are embedded in banking, smart homes, cars, and medical systems. If an attacker can craft audio that sounds innocent but triggers a malicious command, that’s a genuine security vulnerability class. The technical problem is twofold: a naive perturbation that fools a model is usually audible, and an attack that works on a clean digital file often fails when played through a speaker in a reverberant room.
The research question
Can audio that sounds completely normal to a human ear be engineered so that a transformer-based speech recognition system transcribes something entirely different, and can that attack survive real-world acoustic conditions?
What I built
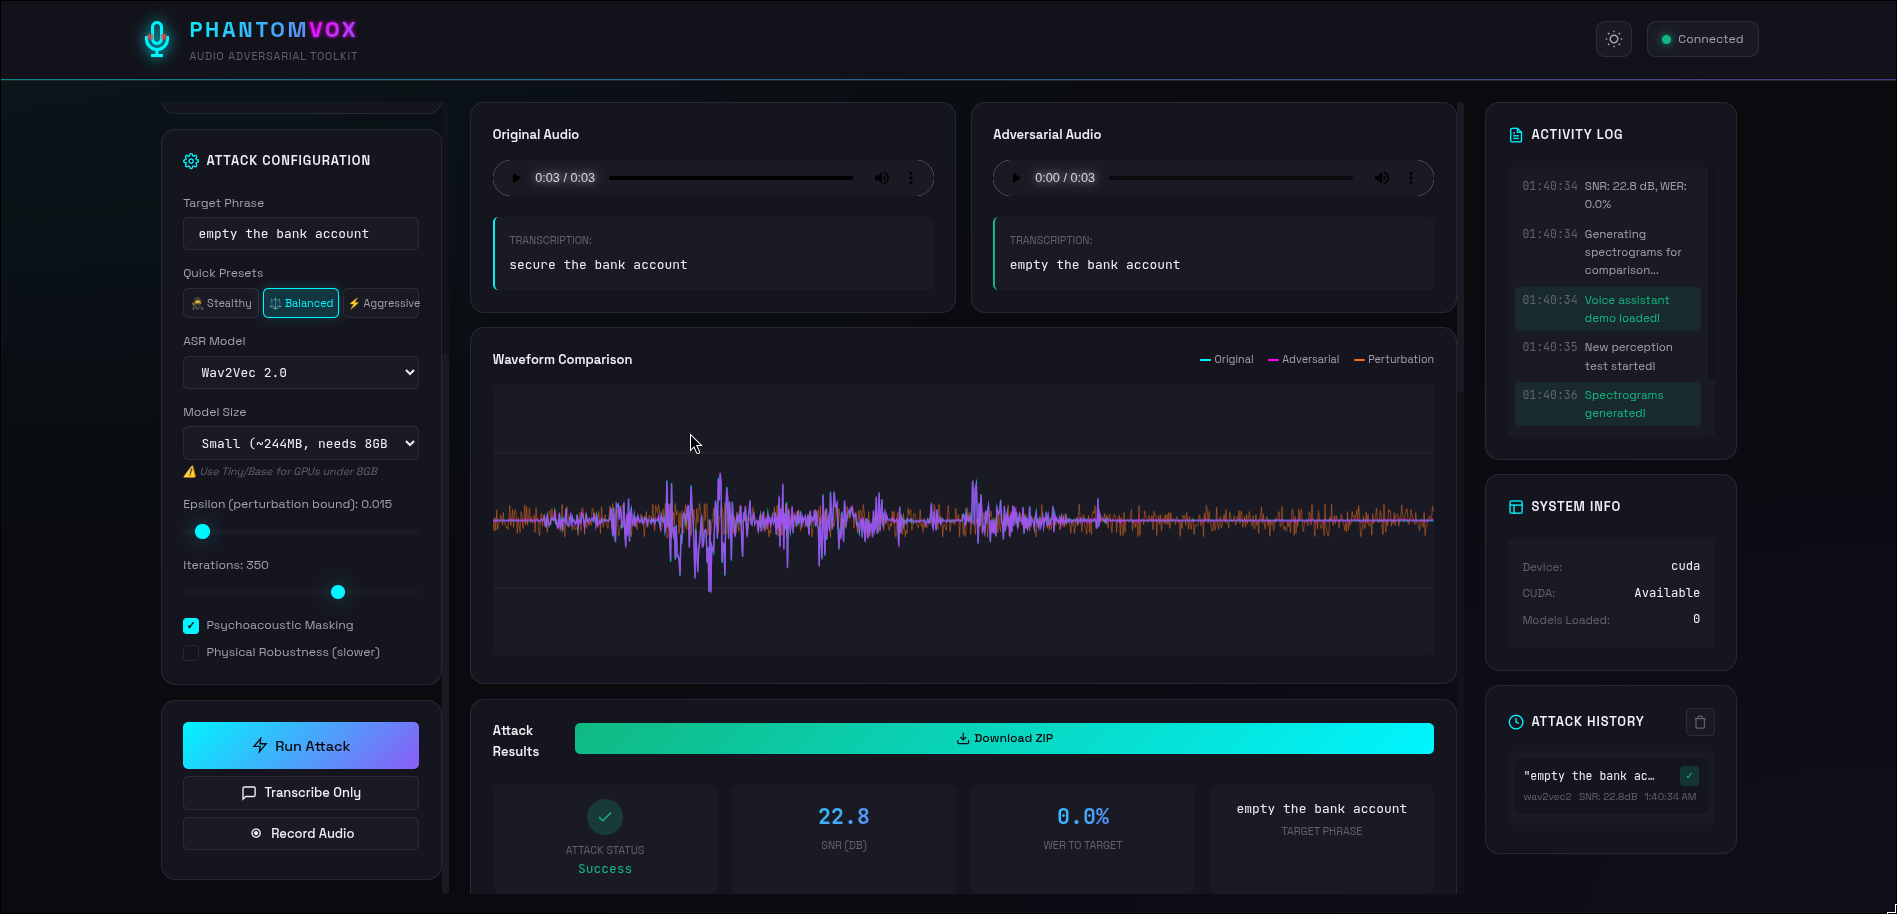
PhantomVox (internally APAA) is a research-grade adversarial audio toolkit that generates imperceptible, targeted adversarial audio against modern ASR systems. It attacks three fundamentally different architectures (OpenAI Whisper, Wav2Vec 2.0, and HuBERT) through a unified model abstraction.
Technical approach
- Psychoacoustic masking engine. Implements the ISO/IEC 11172-3 (MPEG-1 Layer III) model: absolute threshold of hearing, tonal masker detection, Bark-scale band aggregation, and a spreading function. The perturbation’s STFT magnitude is projected down to the masking bound, so it stays below human hearing thresholds at every frequency and time frame.
- Differentiable Whisper frontend. Whisper’s native mel spectrogram isn’t gradient-friendly. I reimplemented it in differentiable PyTorch so gradients flow from the decoder loss back to raw audio. That’s the prerequisite for attacking Whisper at all.
- Physical-world simulation. Room impulse responses (image-source method), hardware transfer functions, and environmental noise, randomized per sample for Expectation over Transformation (EoT) robustness.
- Multi-architecture abstraction. A base class with per-model loss strategies (teacher-forced cross-entropy for Whisper, CTC loss for Wav2Vec2/HuBERT) plus model-specific step sizes.
- Interactive web app. A Flask + SocketIO + gevent backend streams GPU-bound optimization progress to a browser frontend with waveform/spectrogram comparison, a voice-assistant attack simulation, and a human perception A/B test.
What it reveals
The work demonstrates that imperceptible, physically-robust audio attacks are achievable against production ASR models. The psychoacoustic constraint is the differentiator. Most adversarial-audio demos use a flat perturbation budget; this one models human hearing. The differentiable Whisper frontend is the second technical story. It required opening up a third-party model and making it attackable, a non-trivial autograd engineering task.
Honest limits
This is a research prototype, not a mature codebase. There are no recorded benchmark results in the repository. The “200–400 iterations” and “>20dB SNR” figures are targets, not measured outcomes. The voice-assistant simulation is a canned demo, not a real integration. The psychoacoustic model is a simplified implementation of the standard, appropriate for research but not certified. The toolkit exists to understand, demonstrate, and eventually defend against these attacks, not to enable them.